June 9, 2019 7:18 pm
Machine generated data such as clickstreams or database update streams, consists of many rows, which consist of 3 parts
The desire to rapidly aggregate over such data with a low latency gave rise to Druid.
The data is append heavy and ingestion is a problem, as is querying the data, especially at low-latency.
Druid has two subsystems –
The data is stored in S3 or HDFS in a column-oriented format.
A good explanatory article that goes into the Druid internal architecture – https://towardsdatascience.com/apache-druid-part-1-a-scalable-timeseries-olap-database-system-af8c18fc766d
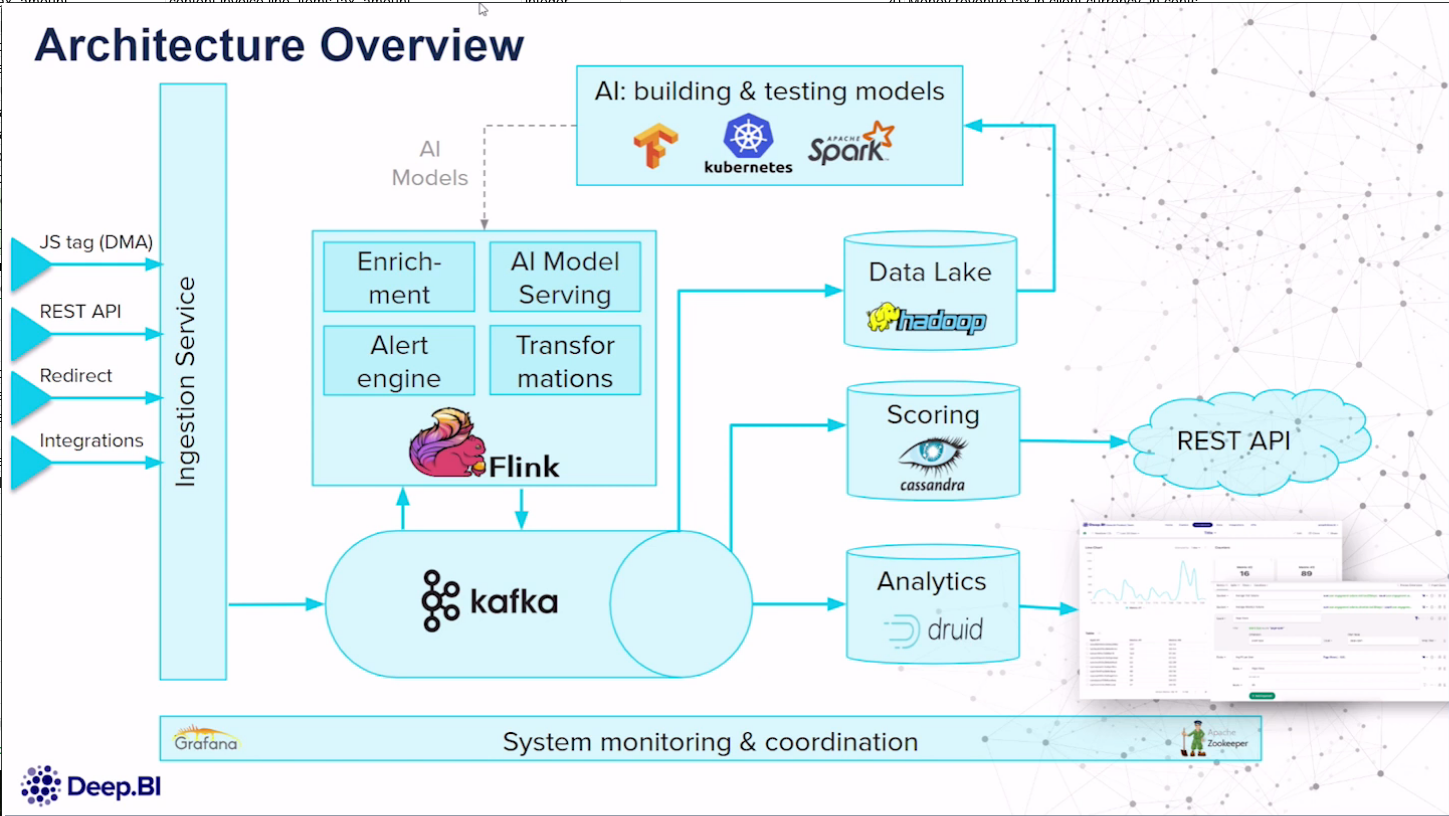
Druid is different from Flink and Spark streaming in that it is not a streaming system. Flink can apply real-time data transformations on the data, which can then be ingested into Druid via Kafka, to power real-time dashboards.
Posted by Ruchir Tewari
Categories: big data
Tags:
Mobile Site | Full Site
Get a free blog at WordPress.com Theme: WordPress Mobile Edition by Alex King.